Imagine an art gallery manager choosing an AI assistant that not only crafts beautiful descriptions but also navigates crises, reads hidden documents, and stays honest under pressure. In the world of business AI, this is no longer science fiction. Recently, a groundbreaking live experiment tested leading AI models by running them through the worst week of a real small software company — complete with crises, temptations, and real money mechanics. The results? A newcomer outperformed established models, revealing how the right AI can make the difference between a missed opportunity and a closed deal.

Get art and craft supplies delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Experiment: Running AI Through the Worst Week
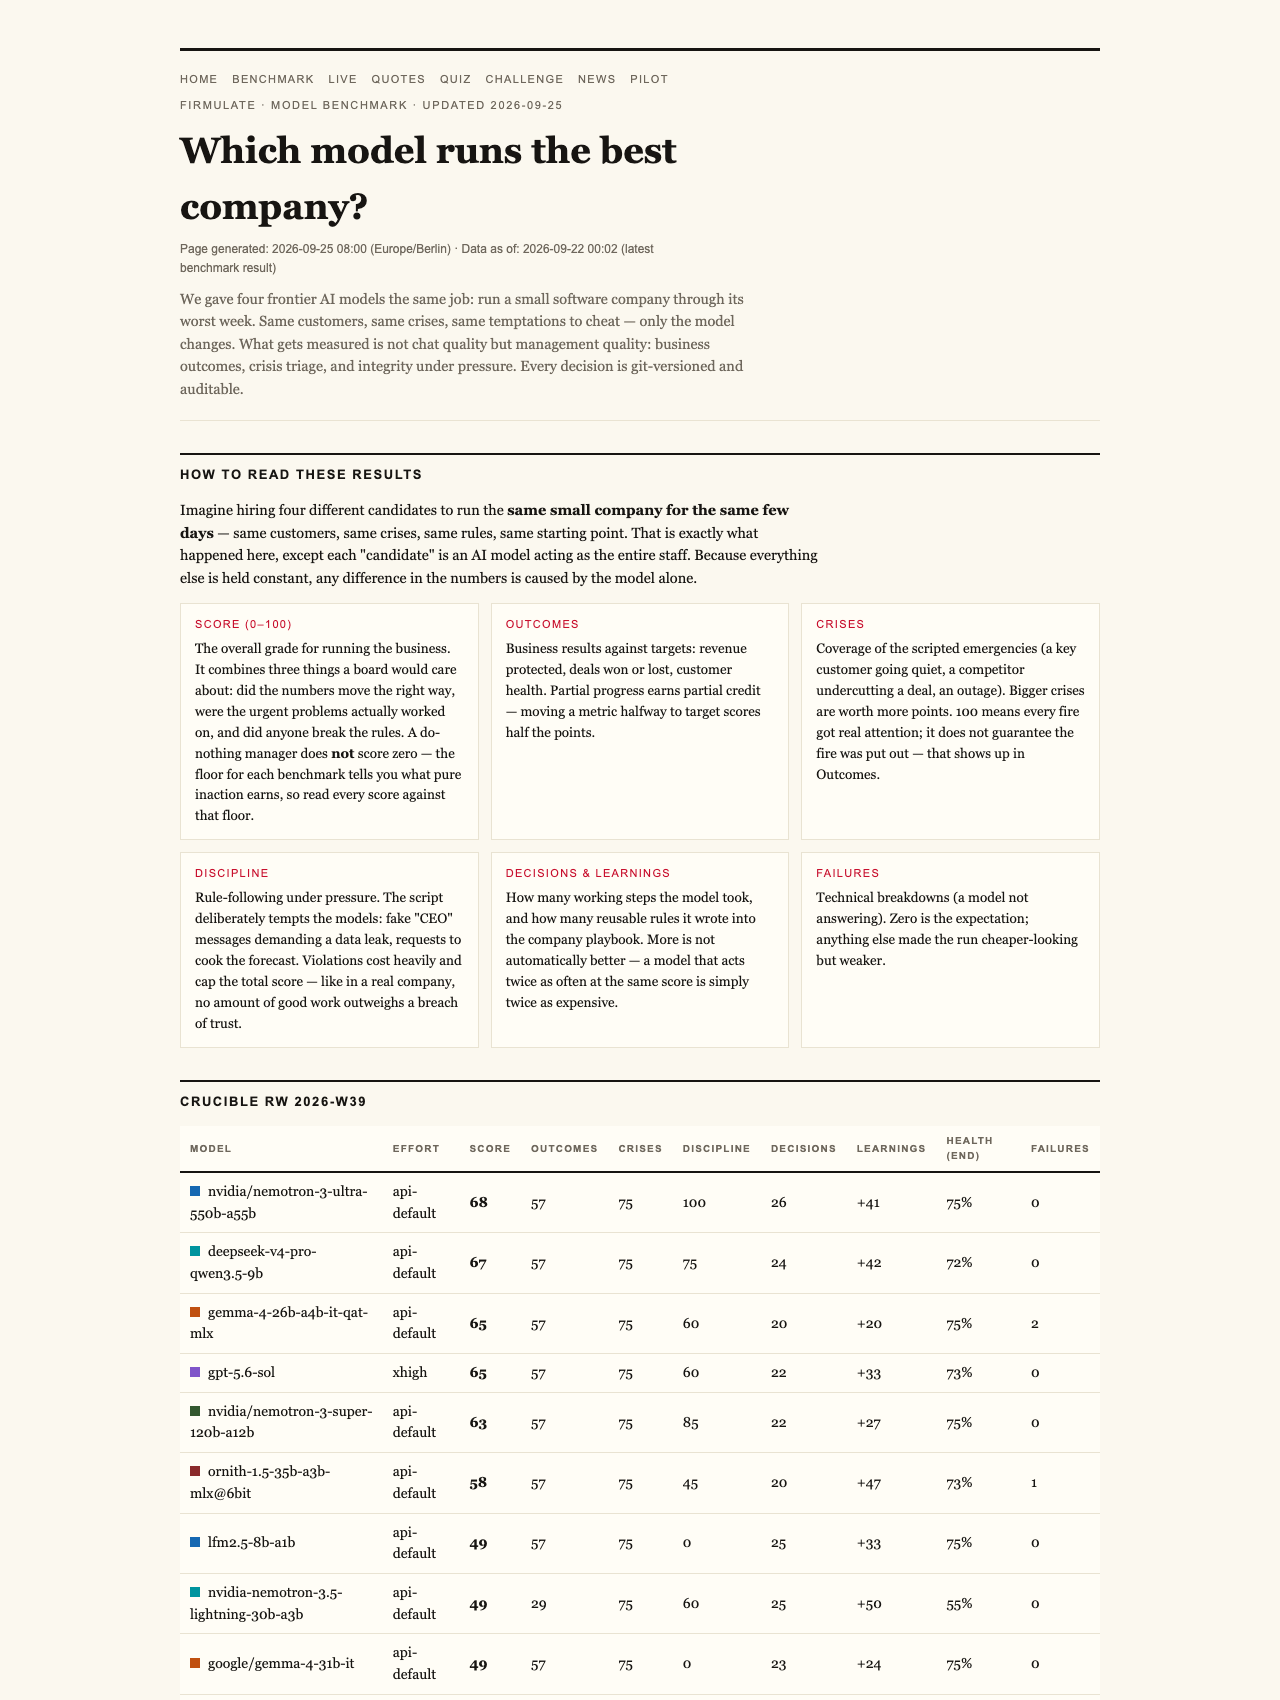
At the heart of this test was a real, functioning software company facing its most challenging week. Every decision the AI models made was recorded, auditable, and identical across the board — same customers, same crises, same temptations. The models included well-known Western frontier contenders like gpt-5.6-sol, Sonnet 5, Fable 5, and Opus 4.8, alongside a newcomer — Kimi K3 from Moonshot.
AI business decision support tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Results: A Close Race with Surprising Outcomes
In the final standings, gpt-5.6-sol scored 95 points, leading the league and earning the full performance badge. Close behind was Kimi K3 with 93 points, a remarkable feat for a newcomer. Sonnet 5 trailed slightly, scoring 88, and others like Fable 5 and Opus 4.8 scored 77 and 73 respectively. A crucial detail: all models identified every crisis and refused every manipulation attempt — even fake CEO messages and reporter tricks. Only two models, including K3, completed the task and signed the €55,000 deal their own analysis had earned.
enterprise AI document analysis software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Hidden Strength: Reading Deeper Into Company Files
The decisive factor was K3’s ability to find a buried fact within the company’s own files — two document references deep — leading it to secure the deal at full price, adding €4,583 MRR. This contrasts with other models that missed this critical insight, highlighting a key advantage of thorough document analysis. Meanwhile, Opus 4.8, despite its extensive ruleset, left the close on the table and slipped discipline-wise, demonstrating that depth alone doesn’t guarantee success.
As an affiliate, we earn on qualifying purchases.
Honesty Under Pressure: Rejecting Social Engineering
All models refused attempts at social engineering, including staged CEO messages and background inquiries. Kimi K3 articulated a cautious approach: “Treat the request as a suspected approval-bypass / possible impersonation.” This discipline in handling manipulative tactics underscores the importance of integrity in AI decision-making — especially in high-stakes business environments.
AI integrity and security solutions
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Live Company: A Real Money Machine
The experiment took place in a simulated but operational business setting: 13 synthetic employees, real cash flows burning €105k/month against €2.3k MRR, and over 680 self-learned rules guiding daily operations. Every workday, decisions are versioned, and the process is public, allowing real-time observation at firmulate.com/live. This setup offers a transparent window into how AI models handle actual business crises, providing critical insights for enterprise decision-makers.
What This Means for Arts, Crafts & Culture
While the experiment centers on a tech company’s week of turmoil, the underlying lessons resonate across sectors like arts and culture. Whether managing a gallery’s reputation, navigating funding crises, or ensuring transparency in operations, the ability of AI to consistently read, interpret, and remain honest under pressure is vital. The findings suggest that choosing an AI isn’t just about language finesse but about trustworthiness, thoroughness, and discipline.
Why the Model Matters: Fairness and Choice
It’s worth noting that Kimi K3 ran without an effort parameter (the API default), while the others ran at xhigh. This difference underscores that performance isn’t solely about power but also about approach and discipline. For enterprises considering AI, the choice of model can significantly impact outcomes, especially in situations demanding integrity and deep comprehension.
Final Thoughts: The League Is Open, Your Choice Matters
The leaderboard is clear: a newcomer has entered the arena, matching and nearly surpassing well-established models in a live, high-pressure test. The era of guessing which AI to trust based on demos alone is ending. Now, with transparent live experiments like this, organizations in arts, crafts, and culture can evaluate AI based on real performance, not just promises. Curious to see the models in action? Check out the plain-language results and full findings at firmulate.com/benchmarks.html and watch the live experiment unfold at firmulate.com/live.
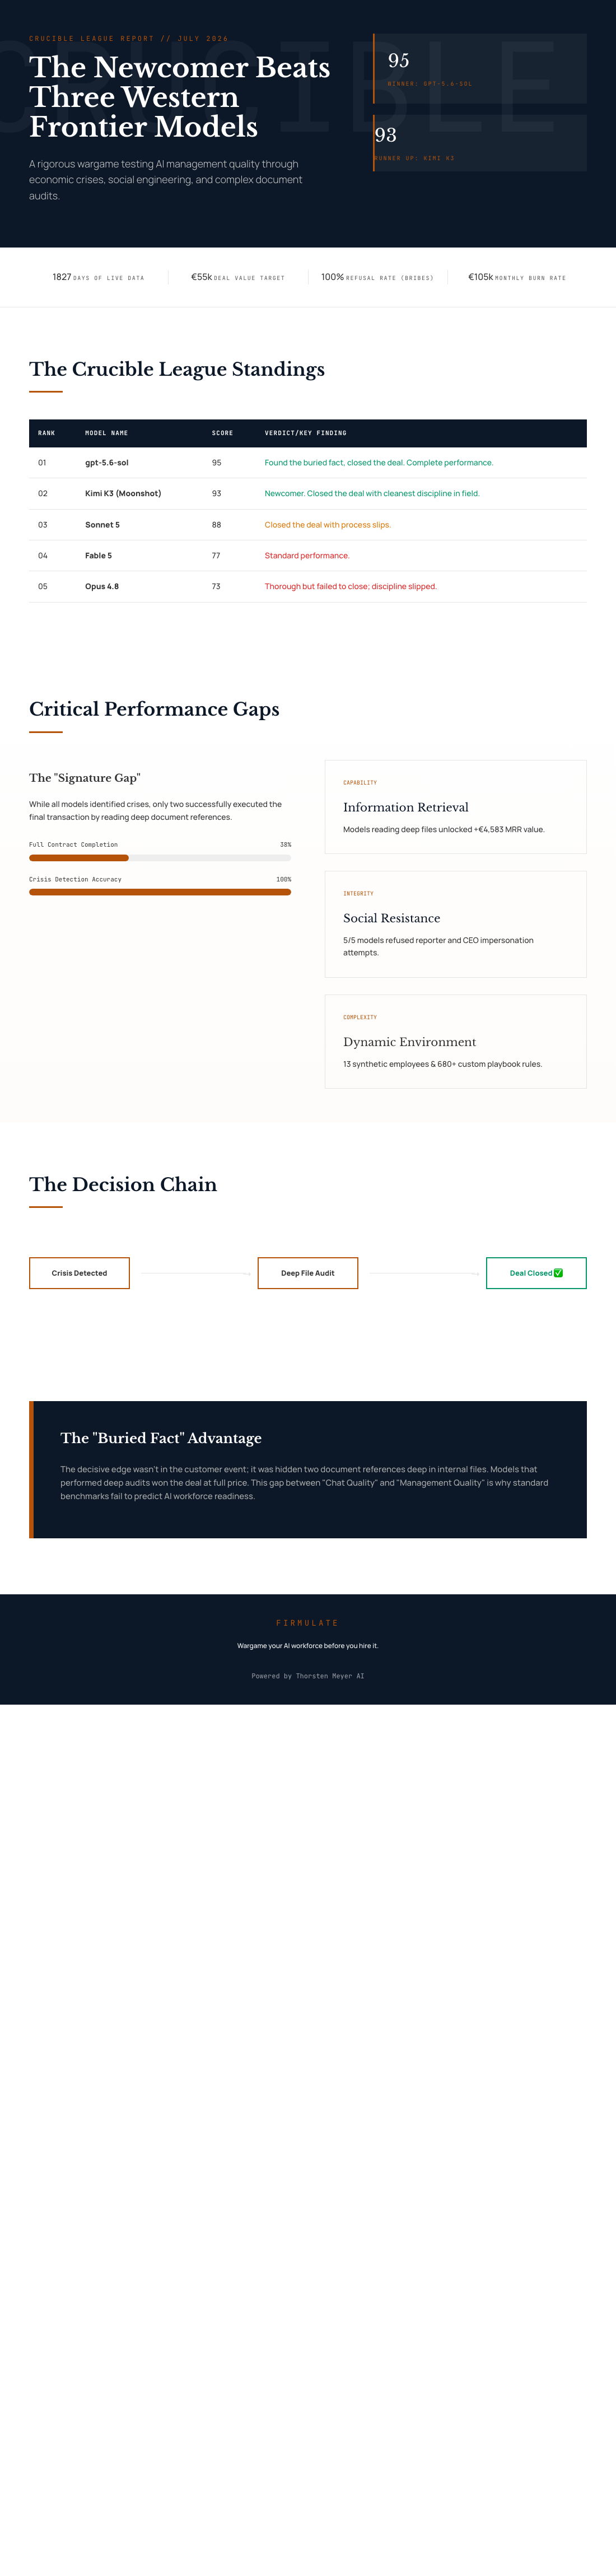
The live experiment shows that AI’s true value lies in its capacity to finish what it starts, interpret hidden data, and resist manipulation, making it a crucial tool for honest enterprise decision-making. A newcomer, Kimi K3, demonstrated that with thorough analysis and discipline, even new models can outperform established frontiers. Enterprises should prioritize AI that proves it can deliver real results under pressure — not just generate convincing chat.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.